If you have ever tried to scrape a list of competitor prices, train an AI model on fresh web content, or build an agent that can actually browse the open internet, you've discovered the central problem of 2026 web data: every site worth scraping now sits behind sophisticated anti-bot walls — Cloudflare, Akamai, DataDome, PerimeterX, Kasada — and a datacenter IP from a typical VPS will get you blocked in seconds. Bright Data is the answer the world's largest enterprises and AI labs reach for. Founded in 2014 in Israel (originally as Luminati Networks, rebranded in 2018), Bright Data has grown into a $300M ARR business with 20,000+ customers — including McDonald's, Pfizer, Deloitte, Moody's, NBC Universal, eToro, Oxford, and the United Nations — running on 400M+ residential IPs across 195 countries, a 99.95% success rate, and one of the most comprehensive web-data product suites in the industry. The platform was named the #1 proxy network on G2's Spring 2026 Enterprise Grid, earns 4.6/5 across 323+ verified G2 reviews and 4.8/5 on Capterra, and ships everything from raw proxies to ready-to-use datasets, AI-ready Web MCP, an Agent Browser, and a free Discover API built specifically for AI agents.
For developers, AI builders, marketers, e-commerce teams, SEO/SERP analysts, financial researchers, and anyone whose work depends on reliable, scaled access to public web data, Bright Data has effectively defined the category. This 2026 review walks through the complete ecosystem — every proxy type, every API, the new AI-agent products, the free tiers, complete pricing breakdown, head-to-head comparisons with Oxylabs and Decodo, honest limitations (especially around pricing), and exactly who should (and shouldn't) sign up.
Bright Data Review 2026: The World's #1 Proxy and Web Data Platform That Powers Web Scraping, AI Training, and Agent Browsing at Petabyte Scale
Overview and Background
Bright Data is a web-data infrastructure company that bundles four major capabilities into one platform: proxy networks (residential, ISP, datacenter, mobile), Web Access APIs (unlocker, browser, SERP, crawl), structured data feeds (scraper APIs, datasets, real-time firehose), and AI-ready agent infrastructure (Web MCP, Agent Browser, Discover API). The core promise is simple: whatever public web data you need, however much of it, and however protected the source — Bright Data has a product that gets you that data reliably, at scale, and within a compliance framework that satisfies enterprise legal teams.
The company was founded in 2014 by Ofer Vilenski and Derry Shribman, originally operating as Luminati Networks before rebranding to Bright Data in 2018. The headquarters is in Netanya, Israel, with US offices in San Francisco and New York. By 2026 the business has crossed $300M ARR and serves over 20,000 paying customers, with its customer logo wall reading like a global Fortune 500 directory — CDN77, Club Med, Deloitte, eToro, McDonald's, Moody's, NBC Universal, Nokia, Oxford, Pfizer, Shopee, Taboola, and the United Nations among them. Independent recognition includes the #1 spot on G2's Spring 2026 Enterprise Grid for proxy networks, a 4.6/5 G2 rating, a 4.8/5 Capterra score, and ISO 27001 and SOC 2 certifications.
The 2026 product map is unusually deep: Proxy Infrastructure (Residential, ISP, Datacenter); Web Access APIs (Unlocker API, SERP API, Browser API, Crawl API, free Discover API); Data Feeds (Scraper APIs across 250+ domains, Scraper Studio, Datasets Marketplace, Data Firehose); Data and Insights (Retail Intelligence, Managed Data Acquisition, Deep Lookup); and a dedicated Data for AI suite covering Video and Audio Data for multimodal training, Video Feeds for VLA humanoid robotics, Search & Extract for AI knowledge, Agent Browser for automated AI actions, and the free Bright Data MCP server — the fastest way for any AI agent to gain reliable web access.
Why Bright Data Stands Out in 2026
The largest residential proxy network in the world: 400M+ residential IPs from real peer devices across 195 countries, with the ability to target any country, city, carrier, and ASN. For scraping sites that aggressively block datacenter IPs (which is most sites worth scraping), this scale is the platform's most direct competitive advantage — and it's why Bright Data ranks #1 on G2's Spring 2026 Enterprise Grid.
A truly complete product suite, not just proxies: Most competitors specialize in one layer — proxies, or scrapers, or datasets. Bright Data ships all of them under one roof, with consistent billing and a unified dashboard. You can start with raw proxies, graduate to the Unlocker API when sites get harder, switch to pre-built Scraper APIs when you need structured data, or skip the engineering entirely and buy from the Datasets Marketplace. One vendor, four levels of abstraction.
Industry-leading 99.95% success rate and 99.99% uptime: Real-time benchmarks consistently show Bright Data's Unlocker API and proxy network outperforming every major competitor on the hardest targets — Amazon, LinkedIn, Google, Cloudflare-protected sites. For production pipelines where failed requests cascade into expensive engineering hours, this reliability premium is the entire reason enterprise teams pay enterprise prices.
Purpose-built AI agent infrastructure: The Bright Data MCP server (free) is the fastest way to give Claude, ChatGPT, or any AI agent reliable web access through the Model Context Protocol. Combined with the Agent Browser (lets agents perform automated browser actions) and the free Discover API (live web discovery for agents), Bright Data has assembled the most credible “agent-ready web” stack on the market — and it's a major reason why AI labs and startups dominate the 2026 customer growth.
Genuine compliance and ethics leadership: Bright Data operates the industry's only multilingual global Compliance & Ethics team, runs an industry-leading KYC process, sources its peer network through verified opt-ins, and is GDPR / CCPA / SEC compliant with ISO 27001 and SOC 2 certifications. For enterprise legal teams that need to defensibly say “we collect only publicly available data” — this is the platform that actually documents it.
Free tiers across the most important products: The Unlocker API, SERP API, Web Scrapers, Scraper Studio, Discover API, and Bright Data MCP all ship with meaningful free tiers — uncommon at this end of the market. Combined with no-credit-card-required signup, this lets developers genuinely evaluate the platform on real workloads before committing.
A real Startup Program and pro bono initiative: The 2026 Startup Program offers AI startups discounted access; the Bright Initiative provides free web-data services to 700+ partner organizations including Princeton, Stanford, Oxford, Duke, and 135+ NGOs.
Key Features and Technology
Bright Data's product surface is unusually wide — but it organizes cleanly into four layers, from raw proxies up to ready-to-use datasets. Here's how the ecosystem breaks down in 2026.
Proxy Infrastructure — The Foundation Layer
Residential Proxies route your requests through 400M+ real peer devices across 195 countries, making your traffic indistinguishable from organic user visits. ISP Proxies (1.3M+) are static residential IPs hosted in datacenters — fast and stable, with residential authenticity. Datacenter Proxies (1.3M+) are the fastest and cheapest option, suitable for less-protected targets. All three share the same proxy manager, zone-based API, and integration patterns — so you can mix and match by target without rewriting code.
Web Access APIs — Skip the Anti-Bot Battle
The Unlocker API handles every anti-bot challenge automatically — CAPTCHAs, JavaScript rendering, fingerprinting, rate limits — and returns clean HTML. SERP API delivers real-time Google, Bing, DuckDuckGo, and Yandex results on-demand. Browser API spins up remote stealth browsers for sites that require full browser context. Crawl API turns entire websites into AI-friendly structured data in a single call. And the free Discover API is specifically built for AI agents that need to find URLs live on the web.
Data Feeds — When You Don't Want to Engineer Scrapers
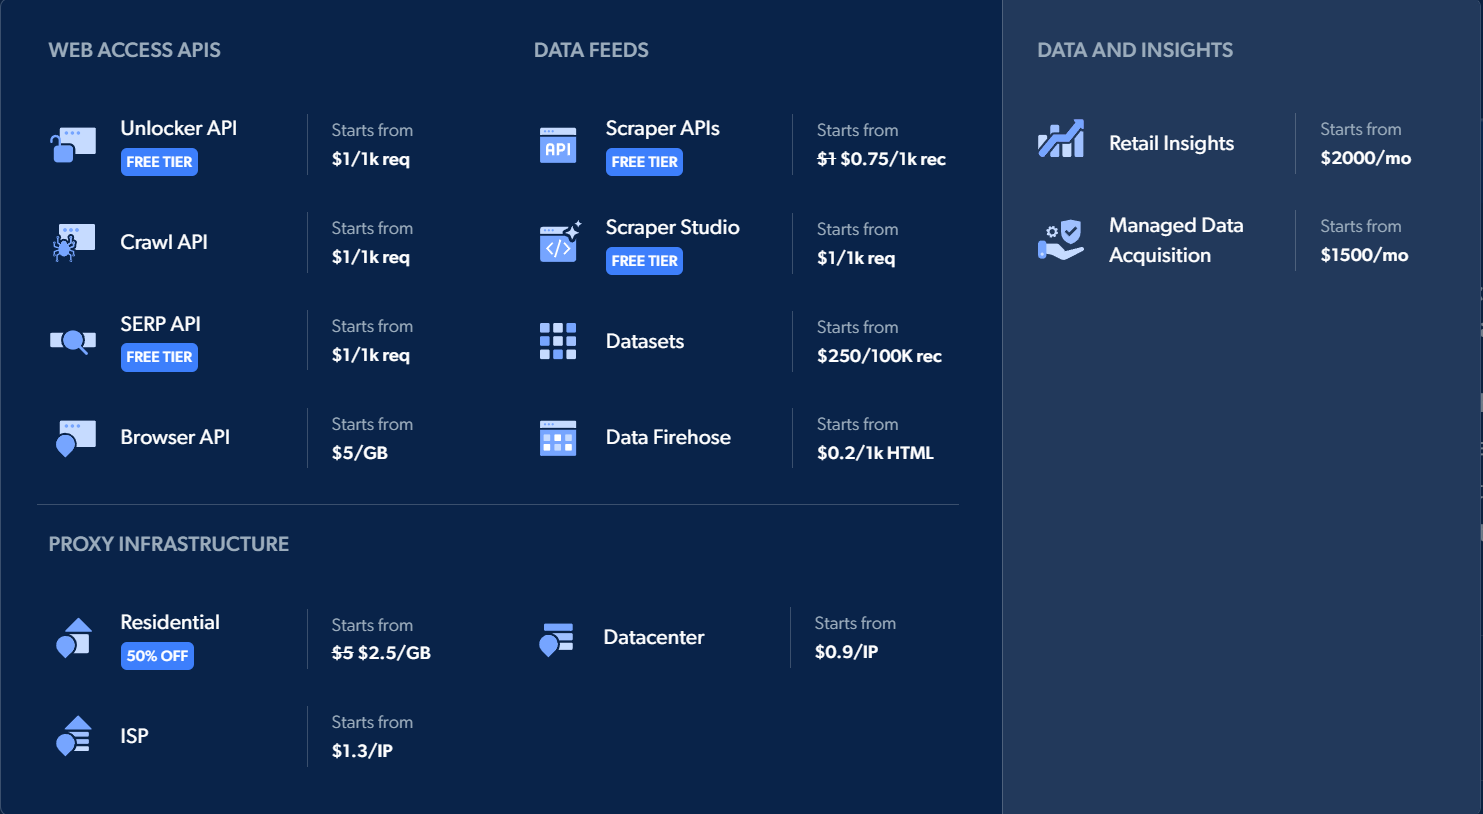
Scraper APIs cover 250+ pre-built scrapers including LinkedIn, e-commerce (Amazon, Walmart, Shopify), social media (Instagram, TikTok, X), and ChatGPT — fetch real-time structured data without building or maintaining any scraping code. Scraper Studio is the AI-powered no-code workflow that turns any website into a data pipeline through natural-language instructions. The Datasets Marketplace ships pre-collected, regularly refreshed structured data from 250+ domains — skip the scraping entirely and just buy what you need. Data Firehose delivers real-time web data as it's collected, ideal for time-sensitive use cases like price intelligence or breaking news monitoring.
Data for AI — Agent-Ready Web Infrastructure
The 2026 flagship investment. Bright Data MCP is a free Model Context Protocol server that gives Claude, ChatGPT, and any agent platform reliable web access in minutes. Agent Browser enables AI agents to perform automated browser actions (form fills, multi-step workflows, authenticated browsing). Search & Extract provides instant knowledge acquisition for AI. Video and Audio Data and Video Feeds for VLA deliver multimodal training data, including specialized feeds for humanoid robot policy training. Data Packages ship LLM-ready datasets tailored per industry. This is the part of Bright Data that's growing fastest in 2026 — and where the platform's compliance posture matters most.
Universal Integrations and Bright Insights
Bright Data integrates with every major AI/ML and data stack: AWS, Databricks, Snowflake, the major orchestrators, and dozens of AI frameworks. Bright Insights packages the underlying data into a Retail Intelligence product with real-time e-commerce dashboards and AI-powered recommendations. Managed Data Acquisition is for teams that want Bright Data to engineer the entire pipeline end-to-end. Deep Lookup (Beta) lets you run complex queries against web-scale data.
Pricing, Plans, and Package Structure
Bright Data uses product-based, pay-as-you-go pricing — you pay only for what you use across each product, with no umbrella subscription. Multiple products ship with meaningful free tiers, no credit card required to sign up, and volume discounts kick in as usage scales. The pricing below reflects publicly listed 2026 starting rates — verify the live price and any active promotion (residential proxies are currently 50% off as of mid-2026) on Bright Data's pricing page before committing.
| Product | Starting Price (2026) | What It Covers | Best For |
|---|---|---|---|
| Residential Proxies | ~$2.5/GB (50% off promo, regular ~$5–$8.40) | 400M+ IPs across 195 countries, real peer devices | Scraping protected sites at scale |
| ISP Proxies | ~$1.3/IP | 1.3M+ static residential IPs | Stable sessions, account-based access |
| Datacenter Proxies | ~$0.9/IP | 1.3M+ high-speed IPs | High-volume scraping of less-protected sites |
| Unlocker API | Free tier + ~$1/1k requests | Bypass blocks, CAPTCHAs, fingerprinting | Production pipelines on protected targets |
| SERP API | Free tier + ~$1/1k requests | Google, Bing, DuckDuckGo, Yandex results | SEO/SERP tracking, AI search agents |
| Scraper APIs | Free tier + ~$0.75/1k records | 250+ pre-built scrapers (LinkedIn, Amazon, social) | Skip building/maintaining scrapers |
| Datasets Marketplace | From ~$250/100k records | Pre-collected data from 250+ domains | Skip scraping entirely, buy ready data |
| Bright Data MCP | Free | Model Context Protocol server for AI agents | AI builders adding web access to agents |
| Retail Insights / Managed Service | From ~$1,500–$2,000/month | Enterprise-managed pipelines + dashboards | Teams wanting outcomes, not infrastructure |
How Bright Data Compares to Alternatives
| Factor | Bright Data | Oxylabs | Decodo (Smartproxy) | Apify |
|---|---|---|---|---|
| Residential IP pool | 400M+ (largest) | ~175M+ | ~125M+ | Uses third-party proxies |
| G2 rating (2026) | 4.6★ (323+ reviews, #1 Enterprise Grid) | 4.5★ (414+ reviews) | 4.6★ (smaller volume) | 4.8★ (developer-focused) |
| Residential entry price | ~$2.5/GB (promo) — $5–$8.40 regular | ~$4–$8/GB | ~$1.5–$4/GB | Pay-per-result model |
| Pre-built scrapers / datasets | 250+ scrapers + Datasets Marketplace | ~50+ scrapers | Limited | 3,000+ community actors |
| AI agent infrastructure | MCP server + Agent Browser + Discover API (all free) | Web Scraper API + limited agent tools | Limited | Strong actor ecosystem |
| Compliance / certifications | ISO 27001, SOC 2, GDPR, dedicated ethics team | ISO 27001, GDPR | GDPR | SOC 2, GDPR |
| Best for | Enterprise scale, hardest targets, AI agents | EU enterprise, structured B2B data | Budget-conscious teams | Developers wanting actor marketplace |
vs. Oxylabs: Oxylabs is the closest direct rival — both target enterprise scraping, both have strong G2 ratings, and both ship structured data products. Bright Data wins on IP pool size (400M+ vs 175M+), product breadth (250+ scrapers vs ~50+), and AI-agent infrastructure depth. Oxylabs has a slightly higher Trustpilot score and stronger EU enterprise concentration. For US/global AI work, Bright Data; for EU-centric B2B data, Oxylabs is the legitimate alternative.
vs. Decodo (Smartproxy): Decodo wins decisively on price — residential at $1.50–$4/GB versus Bright Data's $5–$8.40/GB list rates. For teams under ~100GB/month, the math often favors Decodo. Bright Data wins on success rate against the hardest targets (Amazon, LinkedIn, Cloudflare-heavy), pre-built scraper breadth, and AI infrastructure. Pick by workload: budget scraping → Decodo, production-critical or AI-agent work → Bright Data.
vs. Apify: Apify's developer-marketplace model (3,000+ community-built actors) is genuinely different. For developers who want to build and share scraping code, Apify is the better fit. Bright Data is the better fit for enterprise teams who want pre-built, supported, enterprise-SLA scrapers and infrastructure. Many AI startups end up using both — Apify for niche scrapers, Bright Data for the proxy backbone.
Pros and Cons
What Users Love
Best-in-class success rate on hard targets: Independent benchmarks from Proxyway and Scrapeway consistently rank Bright Data at or near the top for success rate against Amazon, LinkedIn, Google, and Cloudflare-protected sites. For production pipelines where each failed request cascades into engineering hours, this is the platform's most-cited value.
The complete product suite under one roof: One vendor, four levels of abstraction (proxies → APIs → scrapers → datasets), one dashboard, one billing relationship. For teams that want to migrate up the abstraction ladder as their needs mature, this consolidation is genuinely valuable.
Industry-leading customer support: Rated #1 by customers on G2 for support, with under 10-minute average response times and 24/7 coverage. Multiple G2 reviews highlight named account managers who go meaningfully beyond standard SaaS support quality.
Genuine AI-agent leadership: The free Bright Data MCP server, Agent Browser, and Discover API together form the most credible “agent-ready web” stack on the market. AI startups and labs are increasingly defaulting to Bright Data for this reason alone.
Real compliance leadership: ISO 27001, SOC 2, GDPR/CCPA/SEC adherence, a dedicated multilingual ethics team, verified-opt-in peer network, transparent KYC and acceptable use policies. For enterprise legal teams that need to defensibly document their web data sourcing, this is the platform that actually delivers.
Limitations Worth Knowing
Premium pricing at low volumes: Residential proxies list at $5–$8.40/GB versus $1.50–$4/GB at budget competitors. For teams scraping under ~100GB/month, the math frequently favors alternatives. Bright Data's value compounds at scale — at low volumes, you'll likely overpay.
Steep learning curve and dashboard complexity: The dashboard exposes the full product depth, which is powerful but overwhelming. Multiple G2 reviewers explicitly cite learning difficulty. New users typically need a week or two to navigate confidently — or rely on the account team for setup.
KYC process can create friction: Bright Data's industry-leading KYC is great for compliance but can slow down onboarding, particularly for individual developers or use cases that don't fit the standard enterprise mold. Expect to provide business documentation and acceptable-use details before scraping certain targets.
Polarized reviews: The Trustpilot distribution is roughly 85% five-star and 9% one-star — strong when it works, frustrating when billing or onboarding goes wrong. Most one-star complaints cluster around unexpected billing, dashboard confusion, or KYC friction.
Per-GB residential billing surprises: Without careful proxy manager configuration, residential traffic can burn through bandwidth faster than expected — particularly when scraping JavaScript-heavy sites that load many assets. Set bandwidth caps and monitor early.
Overkill for casual scraping: If you need 1,000 product prices once a month from a single retailer, Bright Data is engineering overkill. Simpler tools (ScrapingBee, Apify free tier, even raw Python + Playwright) will get the job done at a fraction of the cost and complexity.
Who Should Use Bright Data
AI builders and agent developers: If you're building an AI agent that needs real-time web access, the free Bright Data MCP server is the fastest credible starting point. Add Agent Browser when your agents need automated actions, and Discover API for live URL discovery. This is the 2026 fastest-growing use case on the platform.
E-commerce intelligence teams: Competitor price monitoring, product research, review tracking, inventory monitoring at scale — Bright Data's pre-built e-commerce Scraper APIs and the Retail Insights product are purpose-built for this workflow. The Datasets Marketplace can skip the scraping entirely.
Market researchers and financial analysts: Real-time signal extraction from public web data — SERP tracking, social sentiment, news monitoring, financial filings, alternative data — is the use case where Bright Data's reliability premium pays off most directly.
Enterprise data engineering teams: Anyone running production data pipelines that need to clear 99%+ success rates against protected sites at scale — Bright Data's Unlocker API plus residential proxies combination is the gold-standard setup. The 24/7 expert support and compliance posture also satisfy enterprise procurement.
SEO and SERP tracking teams: The SERP API (free tier + $1/1k requests) delivers real-time Google, Bing, DuckDuckGo, and Yandex results on-demand — purpose-built for rank tracking, keyword research, and AI search agents that need fresh SERP data.
Academic researchers and nonprofits: The Bright Initiative provides free web-data access to 700+ partner organizations including Princeton, Stanford, Oxford, and 135+ NGOs. If your research has public-interest applications, this is one of the most generous free programs in the industry.
Getting Started: Step by Step
- Create a free Bright Data account. Sign up at brightdata.com with email or a Google account. No credit card required — you get immediate access to free tiers on Unlocker API, SERP API, Scraper APIs, Scraper Studio, and Discover API.
- Pick your starting product based on need. Building AI agents? Start with the free MCP server. Need rank tracking? Go to SERP API. Scraping a hard target like LinkedIn or Amazon? Try the Unlocker API first. Need clean structured data? Browse pre-built Scraper APIs.
- Complete the KYC process early. Some products and target sites require Know-Your-Customer verification before access is granted. Submit your business documentation and acceptable-use information up front to avoid delays mid-project.
- Run a real workload on the free tier. Before paying anything, benchmark Bright Data on a real task — your actual scrape targets, your actual data volumes, your actual success-rate requirements. The free tiers cover meaningful test workloads on most products.
- Set bandwidth and spend alerts. Residential proxy traffic can spike unexpectedly on JavaScript-heavy sites. Configure usage caps, billing alerts, and per-zone limits in the proxy manager before going to production — this single habit prevents most “surprise bill” complaints.
- Choose the right product layer for your workload. Raw proxies for maximum control, Unlocker API for protected targets, Scraper APIs to skip scraping engineering entirely, or the Datasets Marketplace to skip scraping completely. Most teams overpay by buying the wrong abstraction level.
- Engage support early. Bright Data's #1-rated support team can dramatically accelerate setup, especially on enterprise-tier projects. For anything beyond a quick test, asking for an onboarding call with a data expert typically pays for itself within the first week.
Tips for Getting Maximum Value
Always benchmark on free tiers before committing — the Unlocker API, SERP API, Scraper APIs, and MCP server free tiers cover real test workloads and reveal your true cost-per-result before you commit to volume. Watch for the 50% off residential proxy promotions, which routinely run during quarterly campaigns and Black Friday — committing during a promo can drop your effective per-GB cost meaningfully. Match the product to the target: residential for protected sites, datacenter for fast scrapes of less-protected targets, ISP for session-stable workflows like authenticated browsing. Set bandwidth caps and billing alerts in the proxy manager on day one — surprise bills are the single most common Bright Data complaint, and they're entirely preventable. For AI builders, start with the free MCP server before reaching for paid endpoints; it covers a remarkable amount of agent web-access needs with zero spend. Negotiate at volume — Bright Data offers material discounts for committed annual spend, and the sales team is responsive to legitimate scale conversations. If you're a startup, apply to the AI Startup Program for discounted access; if you're an academic or nonprofit, apply to the Bright Initiative for free credits. And lean on the support team — under-10-minute response times and named account managers genuinely accelerate setup, especially for teams new to the platform.
Future Outlook and Final Assessment
The tailwinds favor Bright Data. The global web scraping market is projected to nearly double from $1.17B in 2026 to $2.23B by 2031, AI agents are about to become the dominant consumer of public web data, and the regulatory and ethical bar for web scraping is rising in ways that favor compliance-leading vendors. Bright Data's 2026 bets — the free MCP server, Agent Browser, Discover API, Startup Program — position the platform directly on the growth curve of AI-era web data, while the underlying proxy infrastructure (400M+ residential IPs, 99.95% success rate, ISO 27001 / SOC 2 certifications) keeps the enterprise floor strong. The #1 Enterprise Grid ranking on G2 Spring 2026 confirms the competitive position.
The honest caveats remain: pricing is premium and trips up low-volume teams, the dashboard learning curve is real, KYC can slow onboarding, and the platform is genuinely overkill for casual scraping. But within those boundaries, Bright Data delivers one of the most complete, compliant, and credible web-data infrastructures available in 2026 — at prices that make enterprise-grade data acquisition an easy yes for production teams.
Conclusion
Bright Data has spent 12 years building what is now, by most independent measures, the world's most complete web data platform. The 400M+ residential IPs are the largest pool in the industry, the product suite covers everything from raw proxies to ready-to-use datasets, the AI-agent stack (free MCP server, Agent Browser, Discover API) is the most credible in the market, and the compliance posture earns enterprise legal team trust. The pricing has its quirks — start with free tiers, watch the residential bandwidth, match products to workloads — but the platform itself is one of the most direct answers to “how do I reliably get the web data my business or AI agent needs in 2026?” That's exactly the kind of leverage AI Solutes recommends: pick the platform that makes everything easy, take advantage of the free tiers to benchmark, and put the engineering time you save back into the work that moves your business forward.
Ready to unlock the web's data for your business or AI agent?
Explore more honest reviews, tutorials and tool comparisons to find the right tech for the way you work and live — at AI Solutes, where we make everything easy.
👉 Open Free Account: https://ai-solutes.com/brightdata
👉 Our YouTube Channel: youtube.com/@ai-solutes
👉 Our Facebook Fanpage: Facebook
👉 Our X (Twitter): @AISolutes
- StudyMonkey AI
- Hostinger 2026 Review: Compare AI Website Builder, LiteSpeed Speed, Pricing and hPanel Features
- Does Amazon Music Offer the Best Value in Digital Audio? Evaluating the Amazon Music Subscription Suite
- Higgsfield AI Cinema Studio 2.5 Review 2026: Generate Cinematic AI Video Faster With Hero Frames and Real-Time Editing
- Unlock Seamless Collaboration with Notta AI: Advanced Transcription, Summaries, and Multilingual Support for Modern Teams